
Predict to Skip: Linear Multistep Feature Forecasting for Efficient Diffusion Transformers
Beijing Normal University; Shenzhen University of Advanced Technology
不是简单地复用旧特征,而是用线性多步法预测后续去噪步的输出,变化剧烈时自动校正,并按变化快慢决定跳过几步。最高加速 5.54 倍。
简介
扩散 Transformer 已经成为高质量图像和视频生成的主流架构,但迭代去噪的计算开销很大。现有的免训练加速方法大多假设特征在相邻步之间稳定,直接缓存复用;但连续多步复用旧特征会导致潜变量漂移、画质下降。
我们注意到模型输出在去噪轨迹的大部分区段上变化平滑,因此可以有依据地“预测”而不是简单地“复用”。PrediT 把特征预测建模为线性多步问题:用 Adams-Bashforth 方法根据历史输出外推后续输出,在变化剧烈的区段启用 Adams-Moulton 校正以避免误差累积;动态步长调节机制根据特征变化率自适应地决定预测跨度。在多个基于 DiT 的图像和视频生成模型上,PrediT 最高把延迟降低到原来的 1/5.54,画质损失可以忽略。
方法
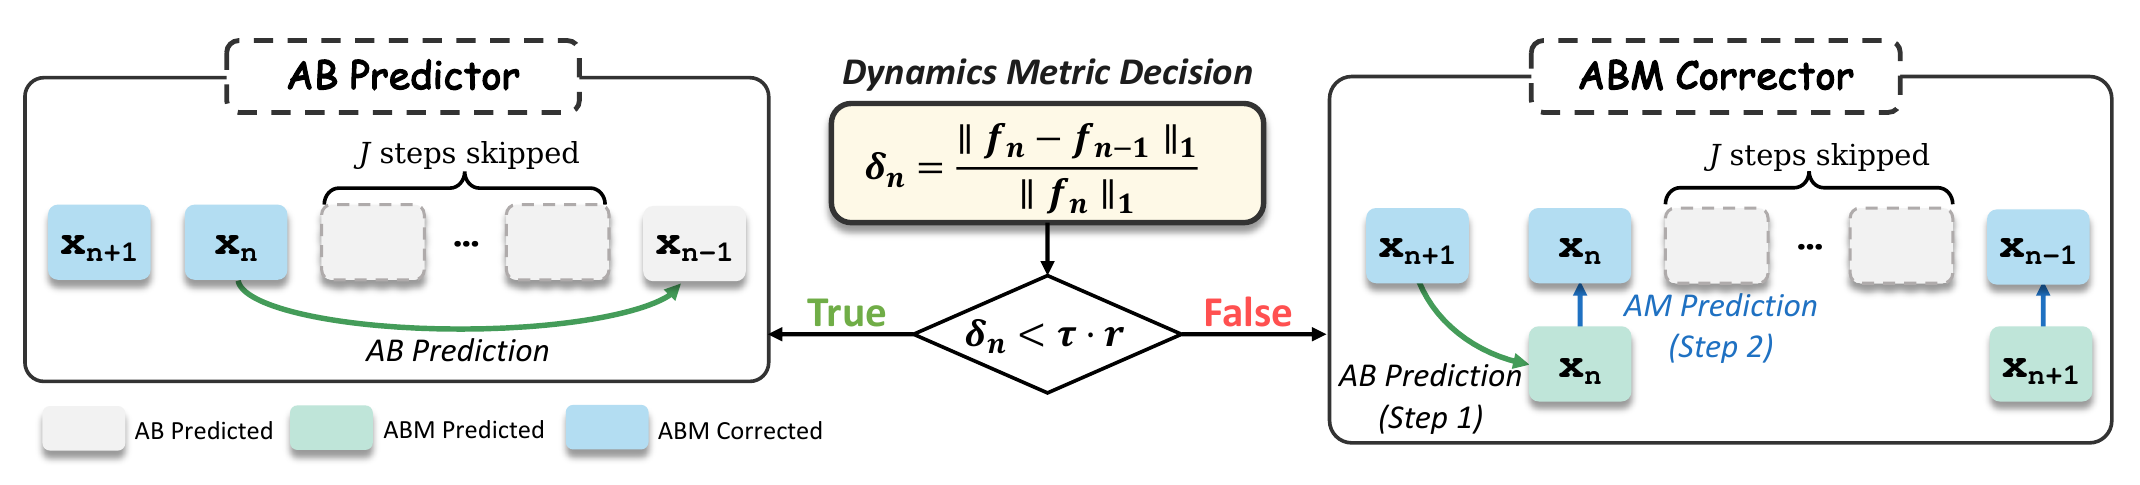
Abstract(英文摘要)
Diffusion Transformers (DiT) have emerged as a widely adopted backbone for high-fidelity image and video generation, yet their iterative denoising process incurs high computational costs. Existing training-free acceleration methods rely on feature caching and reuse under the assumption of temporal stability. However, reusing features for multiple steps may lead to latent drift and visual degradation. As recognized in recent work, model outputs evolve smoothly along much of the diffusion trajectory. We leverage this property to enable principled predictions rather than naive reuse. Based on this insight, we propose PrediT, a training-free acceleration framework that formulates feature prediction as a linear multistep problem. We employ classical linear multistep methods to forecast future model outputs from historical information, combined with a corrector that activates in high-dynamics regions to prevent error accumulation. A dynamic step modulation mechanism adaptively adjusts the prediction horizon by monitoring the feature change rate. Together, these components enable substantial acceleration while preserving generation fidelity. Extensive experiments validate that our method achieves up to 5.54x latency reduction across various DiT-based image and video generation models, while incurring negligible quality degradation.
引用
@inproceedings{cui2026predit,
  title     = {Predict to Skip: Linear Multistep Feature Forecasting for Efficient Diffusion Transformers},
  author    = {Cui, Hanshuai and Tang, Zhiqing and Ma, Qianli and Yao, Zhi and Jia, Weijia and Zhao, Wei},
  booktitle = {Proceedings of the ACM International Conference on Multimedia (ACM MM)},
  year      = {2026}
}