
Not All Frames Deserve Full Computation: Accelerating Autoregressive Video Generation via Selective Computation and Predictive Extrapolation
Edge Intelligence Systems Lab; Shenzhen University of Advanced Technology
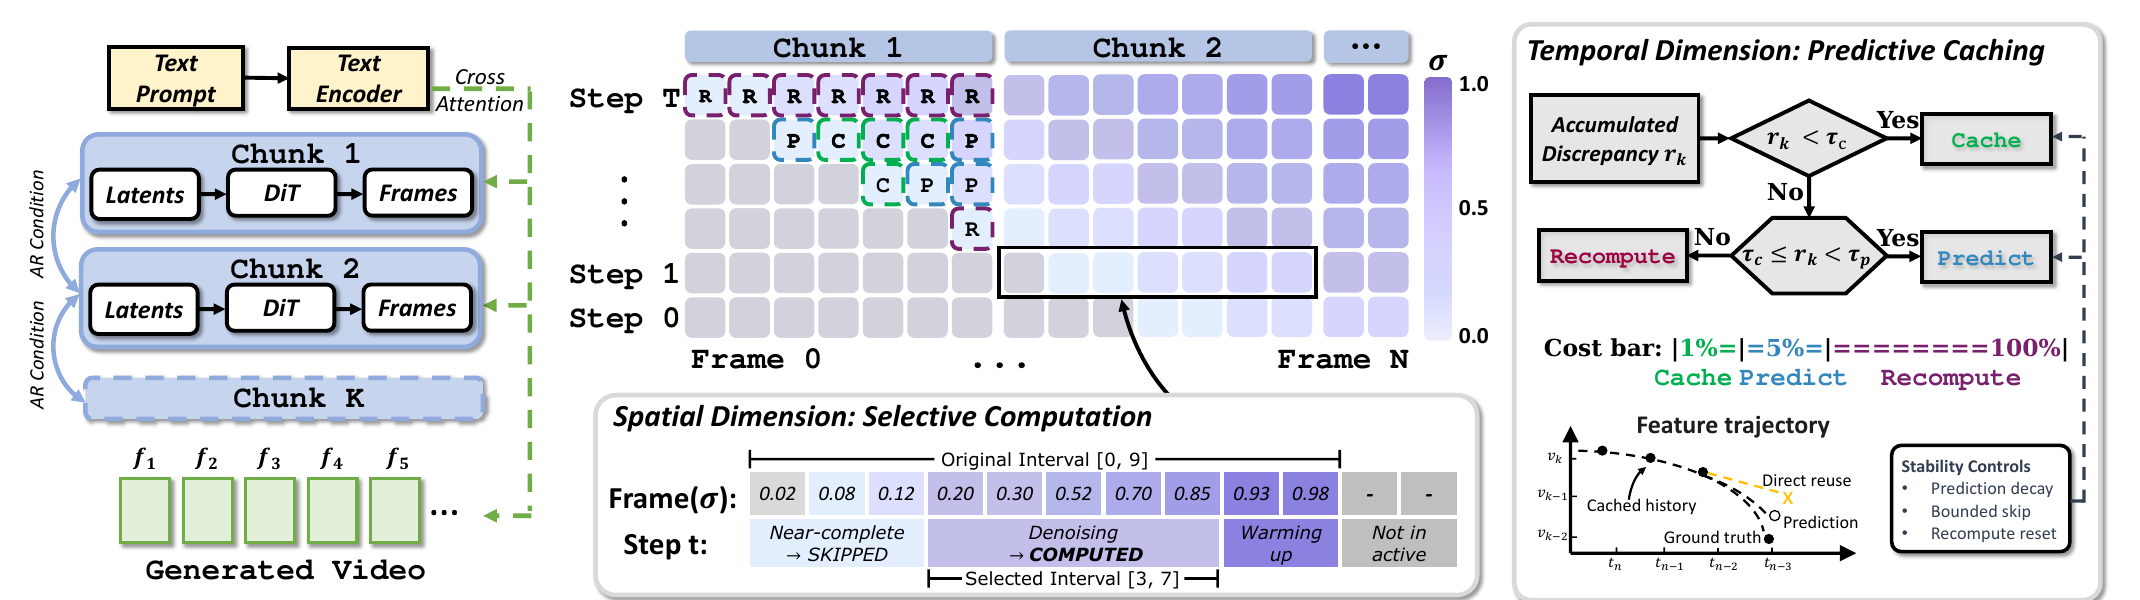
For autoregressive video diffusion, SCOPE adds a predict mode between cache and recompute, and only computes the active frame interval. Up to 4.73× faster on MAGI-1 and SkyReels-V2.
Method
Abstract
Autoregressive (AR) video diffusion models enable long-form video generation but remain expensive due to repeated multi-step denoising. Existing training-free acceleration methods rely on binary cache-or-recompute decisions, overlooking intermediate cases where direct reuse is too coarse yet full recomputation is unnecessary. Moreover, asynchronous AR schedules assign different noise levels to co-generated frames, yet existing methods process the entire valid interval uniformly. To address these AR-specific inefficiencies, we present SCOPE, a training-free framework for efficient AR video diffusion. SCOPE introduces a tri-modal scheduler over cache, predict, and recompute, where prediction via noise-level Taylor extrapolation fills the gap between reuse and recomputation with explicit stability controls backed by error propagation analysis. It further introduces selective computation that restricts execution to the active frame interval. On MAGI-1 and SkyReels-V2, SCOPE achieves up to 4.73x speedup while maintaining quality comparable to the original output, outperforming all training-free baselines.
Citation
@inproceedings{cui2026scope,
  title     = {Not All Frames Deserve Full Computation: Accelerating Autoregressive Video Generation via Selective Computation and Predictive Extrapolation},
  author    = {Cui, Hanshuai and Tang, Zhiqing and Yao, Zhi and Meng, Fanshuai and Jia, Weijia and Zhao, Wei},
  booktitle = {Proceedings of the ACM International Conference on Multimedia (ACM MM)},
  year      = {2026}
}
More projects
DiT block features barely change during intermediate denoising steps. BWCache caches and reuses them block by block, giving up to 2.6× speedup with comparable visual quality and no training.
PrediTACM MM 2026Instead of naively reusing features, PrediT forecasts future denoising outputs with linear multistep methods, corrects in high-dynamics regions, and adapts how many steps to skip. Up to 5.54× faster.