
BWCache: Accelerating Video Diffusion Transformers through Block-Wise Caching
Edge Intelligence Systems Lab
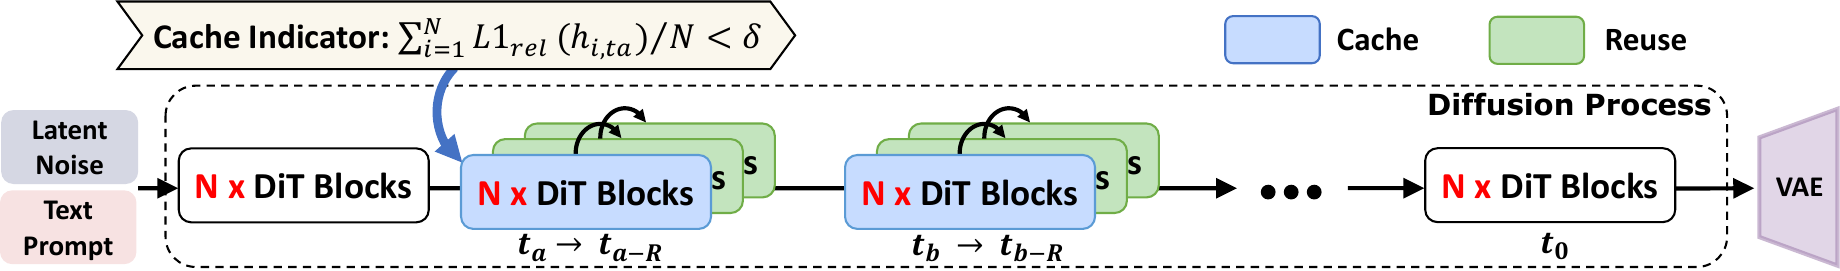
DiT block features barely change during intermediate denoising steps. BWCache caches and reuses them block by block, giving up to 2.6× speedup with comparable visual quality and no training.
Method
Abstract
Recent advancements in Diffusion Transformers (DiTs) have established them as the state-of-the-art method for video generation. However, their inherently sequential denoising process results in inevitable latency, limiting real-world applicability. Existing acceleration methods either compromise visual quality due to architectural modifications or fail to reuse intermediate features at proper granularity. Our analysis reveals that DiT blocks are the primary contributors to inference latency. Across diffusion timesteps, the feature variations of DiT blocks exhibit a U-shaped pattern with high similarity during intermediate timesteps, which suggests substantial computational redundancy. In this paper, we propose Block-Wise Caching (BWCache), a training-free method to accelerate DiT-based video generation. BWCache dynamically caches and reuses features from DiT blocks across diffusion timesteps. Furthermore, we introduce a similarity indicator that triggers feature reuse only when the differences between block features at adjacent timesteps fall below a threshold, thereby minimizing redundant computations while maintaining visual fidelity. Extensive experiments on several video diffusion models demonstrate that BWCache achieves up to 2.6× speedup with comparable visual quality.
Citation
@inproceedings{cui2026bwcache,
  title     = {BWCache: Accelerating Video Diffusion Transformers through Block-Wise Caching},
  author    = {Cui, Hanshuai and Tang, Zhiqing and Xu, Zhifei and Yao, Zhi and Zeng, Wenyi and Jia, Weijia},
  booktitle = {International Conference on Learning Representations (ICLR)},
  year      = {2026}
}
More projects
Instead of naively reusing features, PrediT forecasts future denoising outputs with linear multistep methods, corrects in high-dynamics regions, and adapts how many steps to skip. Up to 5.54× faster.
SCOPEACM MM 2026For autoregressive video diffusion, SCOPE adds a predict mode between cache and recompute, and only computes the active frame interval. Up to 4.73× faster on MAGI-1 and SkyReels-V2.